Automatic Tender Document Processing and Offer Generation
- Partner
- FEGA & Schmitt Elektrogroßhandel GmbH
- Period
- Aug 2023 – Nov 2024
- Focus
- Industry Project
Key outcomeAccuracy@3 of 95 percent and Precision@3 of 90 percent: a relevant product appeared among the first three retrieved results in 95 percent of evaluated cases, at 90 percent precision
Context
Tender documents and product catalogs often describe the same technical requirement in different words, so keyword search misses relevant products even when a good match exists.
Inputs
- Tender documents in PDF and text formats
- Product catalogs and internal databases
Approach
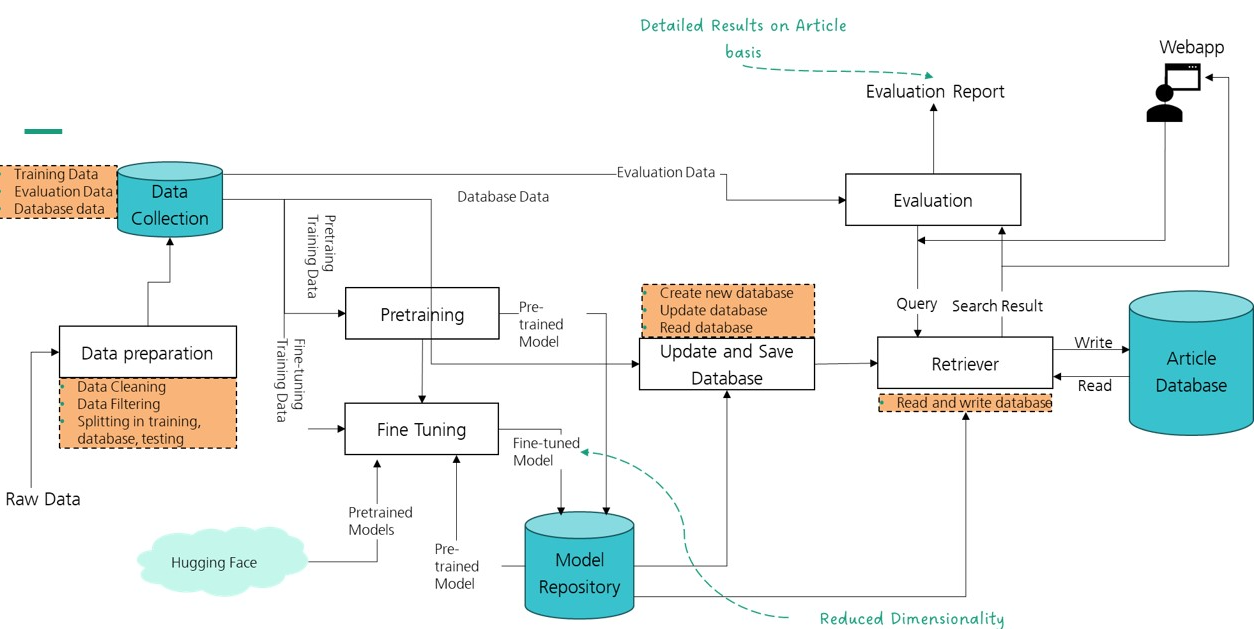
- Designed a semantic search and retrieval system using LLMs and vector databases
- Implemented document parsing, metadata extraction, and ranking strategies
- Built API-based integration components toward deployment in partner infrastructure
Outcomes
- Accuracy@3 of 95 percent and Precision@3 of 90 percent: a relevant product appeared among the first three retrieved results in 95 percent of evaluated cases, at 90 percent precision
- Faster search and offer preparation compared with manual lookup
- Deployed into production on Databricks, followed by code handover and a knowledge-transfer workshop
- Enterprise search is rarely just about matching words; it requires understanding how customers, engineers, and catalogs describe the same requirement differently